
Type a question into a search box and results appear in a fraction of a second. It feels like the engine is searching the internet right then. It isn’t. It is searching a copy, built in advance and kept constantly refreshed, called a web search index, and making and maintaining it is among the more expensive undertakings in computing.
Step one: crawling
A crawler is a program that visits web pages, reads them and follows their links to find more. It must do this politely, respecting rules sites publish about what may be fetched and not hammering a server with requests. The web has billions of pages, many of them duplicates, spam or generated on the fly with endless variations of the same URL. A crawler needs strategies to avoid wasting effort in those traps.
Freshness complicates matters. A news site changes by the minute, a company’s about page maybe once a year. The crawler must decide how often to return to each page, and a mistake means stale results or wasted resources.
Step two: understanding and storing the web search index
Fetched pages are parsed to extract text, links, language and structure. Pages built with heavy scripts need to be rendered, similar to how a browser works, which takes much more computing power than reading plain text. The content is then organized into an inverted index, a structure much like the index at the back of a book: for each word, a list of pages that contain it. Additional layers capture meaning, so that a search for a phrase can match pages that use different words for the same idea.
All this has to sit across many machines, replicated for reliability and arranged so a query can fan out and come back in milliseconds.
Step three: ranking
Finding pages that contain the words is the easy half. Deciding which ten to show first is the difficult one. Ranking draws on hundreds of signals: how well the page matches the query, how trustworthy the site seems, how other sites link to it, how people interact with results, location, language and more. Then there is a constant battle against manipulation, as people try to game the rankings with spam and tricks. Quality takes years of tuning and a lot of human evaluation.
Why so few players have their own web search index
Between crawling, storage, ranking and spam fighting, the up-front and ongoing costs are enormous. Added to that, an engine needs query volume to learn what users find helpful, and volume comes from users, which a newcomer lacks. That chicken-and-egg problem explains why a handful of companies dominate, and why many smaller search brands depend on someone else’s results.
Those smaller brands usually fall into a few types. Some license results from a large index and add their own interface, privacy policy or business model, such as planting trees with ad revenue or promising not to profile users. Some blend several sources. Some operate a limited independent index for particular languages or regions and fill in the rest from partners.
Scale makes the numbers hard to picture. Even a modest web search index must store the text of a huge number of pages, plus the links between them, plus signals about each page’s quality, and it must update all of that continuously. A page that was accurate yesterday may be gone or rewritten today. Keeping a web search index fresh is like repainting a bridge: by the time you finish one end, the other end needs attention.
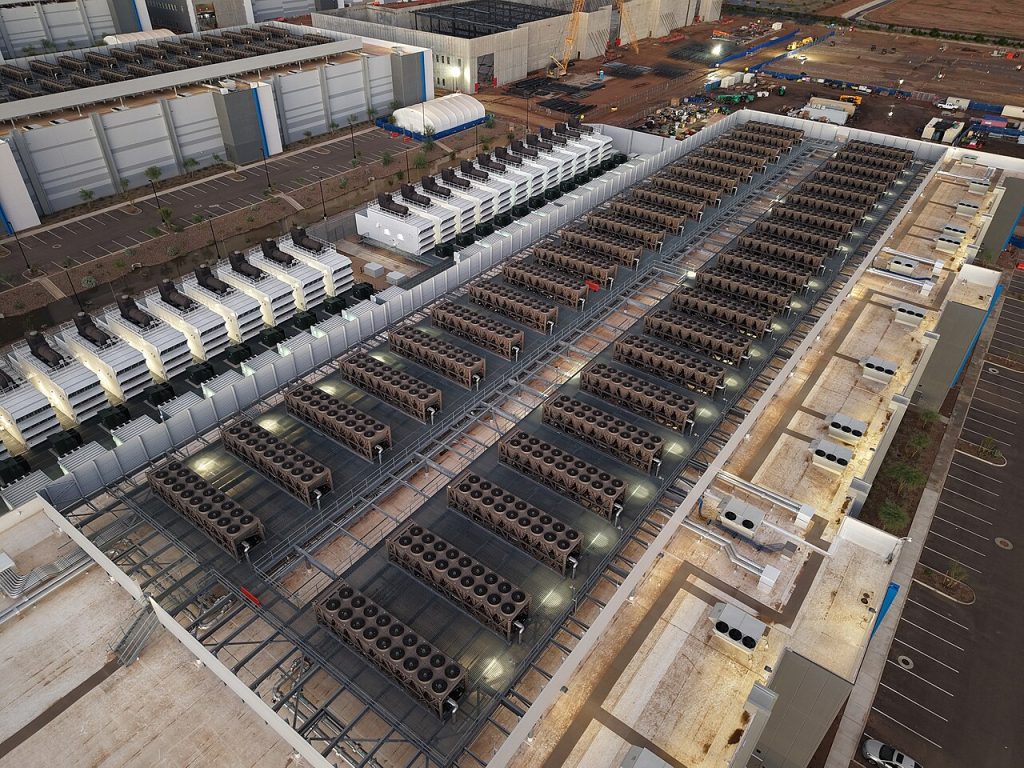
The machines behind it are the same racks and cooling systems that power cloud services, so costs track hardware and energy prices. Constant data refresh is a problem in other industries too, such as the fulfillment centers described in how warehouse robots bring goods to pickers, and small delays add up everywhere, as why checkout pages feel slow shows. Wikipedia’s article on search engine indexing is a good place for the technical basics.
The case for a shared, open web search index
One proposal gaining attention, particularly in Europe, is to build an index as shared infrastructure that multiple engines could use. The argument is that if the expensive base layer is common, competition can happen on ranking, interface and values rather than on who can afford the biggest crawl. Supporters point to benefits for privacy, local-language quality and resilience. Skeptics ask who pays for it, who governs it, and whether engines using the same base will really differ enough to matter. Both sides raise fair points, and the answer depends on execution.
What to look for as a user
- Find out where an engine’s results come from. Reputable ones say so in their documentation.
- Read the privacy policy to see what is logged and for how long.
- Test it on your own typical searches, including ones in your language and about your local area.
- Check how ads are labeled.
Switching your default engine is a small act, and it takes a minute. If you’re curious how it feels, try one for a week and keep a note of how often you went back to your old one. That tells you far more than any announcement.
The short version: a web search index is expensive because the web is huge, messy and always changing. Few companies can afford one, which is why most alternatives borrow results from others. Knowing where your engine’s web search index comes from tells you whose priorities shape what you see.
Image: Rsparks3 / Wikimedia Commons, CC0.



