Picture a payment page that suddenly returns errors at two in the morning. Incident management tools exist for moments like this one. They do not fix the bug, but they organise the people who will.
A bad night, step by step
First, a monitoring system notices the errors. Someone has to wake up, work out which service is failing, tell customer support, and keep the company informed while engineers dig in.
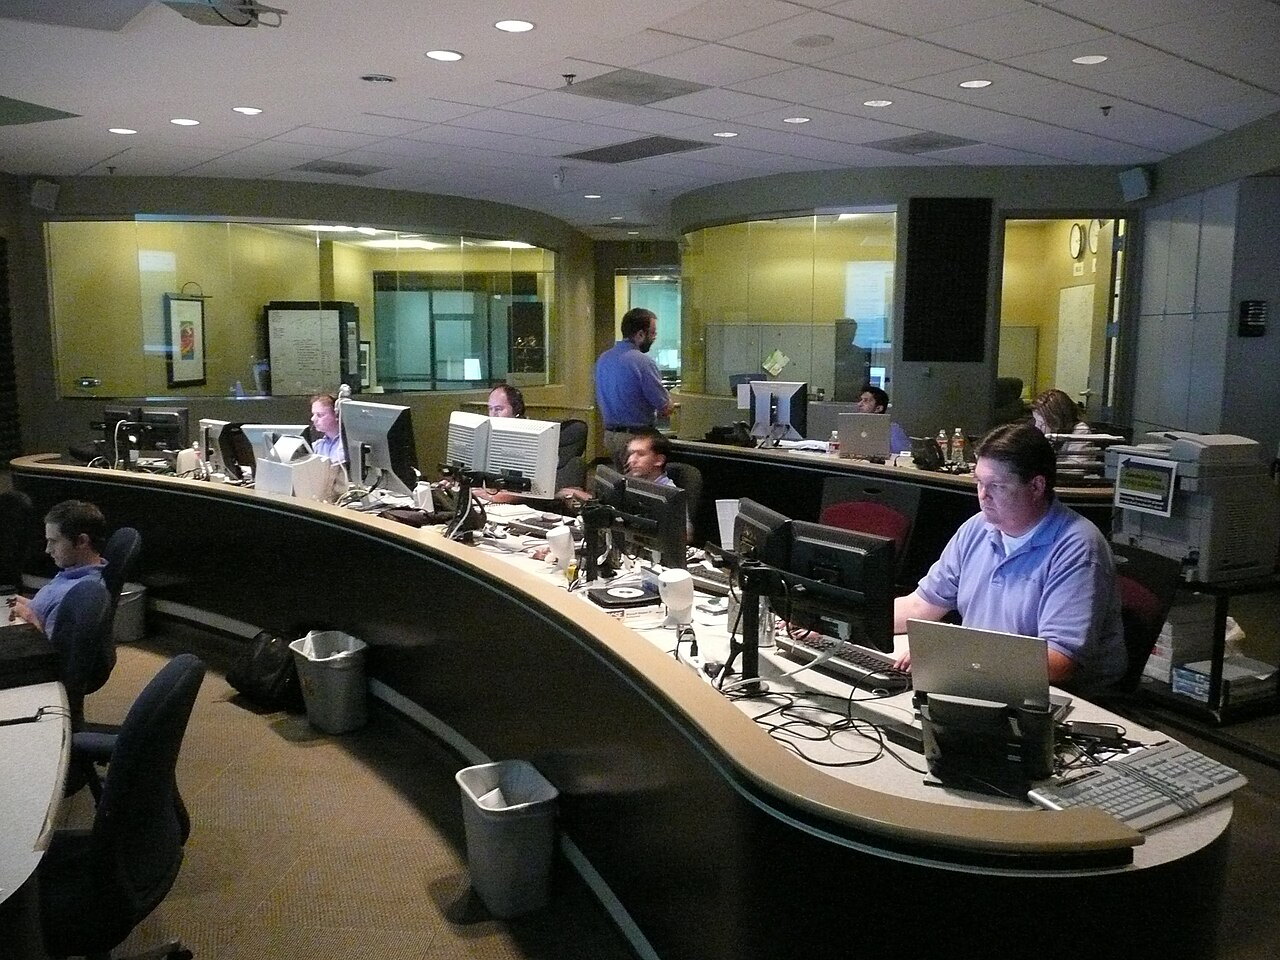
Without a clear process, this turns into a chat thread where five people ask the same question and nobody owns the problem. The tools replace that scramble with a repeatable routine.
The core jobs incident management tools handle
Products differ in polish and price, but most cover the same set of tasks.
- Alerting: receiving signals from monitoring systems and deciding who to notify by call, text or app.
- On-call scheduling: rotations, holiday overrides and backups in one place.
- Escalation: moving to the next person if nobody acknowledges an alert.
- Coordination: a dedicated channel that collects updates and decisions.
- Status updates and records: public pages plus a timestamped history.
None of this is exotic. The value comes from having it connected, so nobody is copying information between five tabs while the site is down.
Many teams also assign roles during a serious incident. One person leads, another handles communication, and others investigate. Good incident management tools make those roles visible so nobody has to ask who is in charge.
Why on-call fairness matters
An alert system that always wakes the same person will burn that person out. Scheduling features spread the load, and good teams look at how often people are paged at night.
Noise is the other enemy. Good incident management tools let you group related alerts, silence known issues during maintenance and set priorities, so the real signal stands out. If every minor blip triggers a call, people start ignoring pages. Tuning alerts so that only urgent problems wake someone is one of the quietest but most valuable jobs in operations.
Smaller companies sometimes begin with a shared phone number and a spreadsheet. That works until the first serious outage, when the spreadsheet is out of date and the person listed is on a flight.
What to compare before you choose
When comparing incident management tools, start with integrations. The tool should connect to your monitoring, chat and ticketing systems without custom glue. Then check how reliable its own notifications are, since an alert service that fails during an outage is worse than none.
Look at pricing as the team grows. Many vendors charge per user, and occasional responders can multiply the cost. Check whether stakeholders who only read updates need paid seats.
Finally, test the mobile experience. Most pages are acknowledged from a phone in the dark, so a clumsy app is a real flaw. Run a few practice alerts before committing, and ask vendors for a trial and a sample incident report so you can see real output, not just the demo.
Switching later is easier than people fear, but moving schedules and routing rules takes planning. The same discipline applies when any workplace system disappears, as in our guide to what to do when a team chat tool is being discontinued.
After the fire: reviews and learning
The record created during an incident feeds the review that follows. Teams that run blameless reviews focus on how the system and process allowed the failure, rather than on who pressed the wrong button.
That habit matters more than any product feature. Incident management tools can collect the timeline, but people still have to ask what went wrong, what helped, and what to change. This kind of operational thinking links closely to the work described in what a chief technology officer for AI infrastructure actually does.
Reliability engineering has its own body of ideas. The site reliability engineering article is a good place to start.
Choosing between simple and heavy setups
Not every team needs the full package. A five-person company can often get by with a paging service, a shared channel and a simple template for post-incident notes. A large organisation, with dozens of services and teams, benefits from deeper incident management tools that map services to owners and route alerts automatically.
Think about runbooks as well. A runbook is a short document that says what to check when a given alert fires. The best incident management tools link the right runbook to the alert, so a half-asleep engineer sees the first three steps at once.
Customer communication deserves a plan. During an outage, silence is worse than bad news. A status page that is updated every thirty minutes, even with the message that investigation continues, builds trust. Decide in advance who is allowed to post, and what tone to use.
Finally, practise. Some teams run game days, where they simulate a failure and watch how the tools and people respond. These drills expose gaps such as a missing phone number, a wrong escalation path or an alert that goes nowhere. It is far cheaper to find those gaps on a quiet afternoon than in the middle of a real outage.
If your team is small, begin with a simple setup: one on-call rotation, one alert route and one place to post updates. Add features only when a real incident shows you need them. Well-chosen incident management tools should make bad nights shorter and calmer, not add another system to babysit.