When you tap a card at a till or press pay on a checkout page, a decision happens before the spinner stops. Somewhere a system has weighed the purchase against what it knows and decided whether it looks like you. Most of the time transaction fraud detection gets it right and you never notice. When it isn’t, you get a declined card at a restaurant or, worse, a thief’s purchase slips through.
What transaction fraud detection models look at
A fraud model takes a payment and turns it into a set of signals. The amount, the merchant type and the time of day are obvious ones. More revealing are comparisons: is this device one the customer has used before, is the shipping address new, does the typing speed match the usual pattern, is the location plausible given the last purchase an hour ago on another continent? Hundreds of such features can feed in.
Many also look at relationships. If the same device, address or email fragment appears across many unrelated accounts, that cluster is suspicious in itself. Graph-based methods are good at this, because organized fraud rings reuse infrastructure to save effort.
Rules versus learning
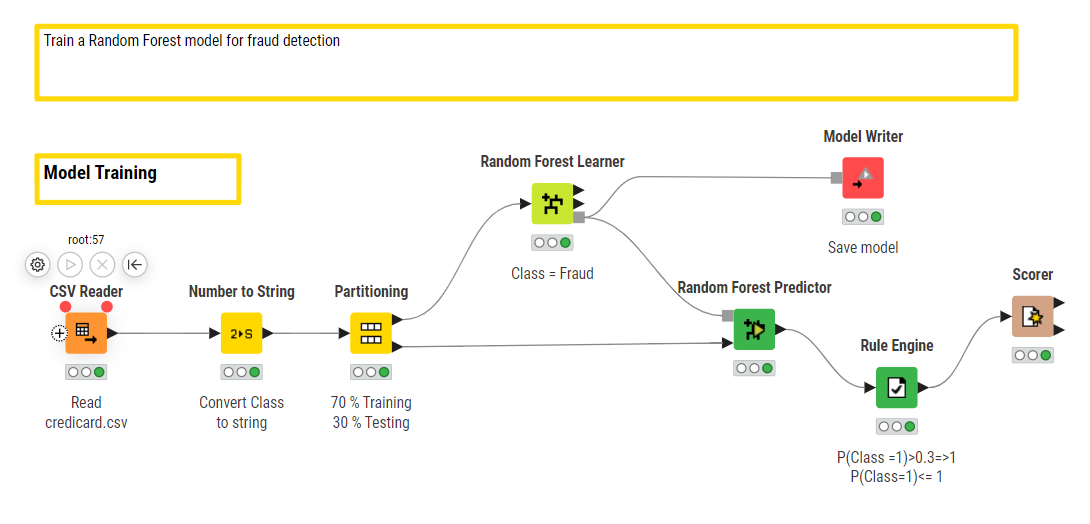
Older systems relied on hand-written rules: block orders above a certain amount from a high-risk country, flag more than three attempts in a minute. Rules are easy to explain and quick to deploy, but fraudsters learn them and route around. Machine learning models find patterns that a person wouldn’t write down, and can update as behavior shifts.
In practice, most teams use both. Rules handle policy and clear-cut cases, and the model scores the gray zone. A common output is a risk score, with thresholds that decide whether to approve, decline or send for extra verification such as a one-time code.
The labeling problem
Training a model requires examples marked as fraud or legitimate. The label often arrives late: a chargeback might appear weeks after the purchase. That delay means the model learns from the past while attackers are already using new tricks. Many cases are never labeled correctly, since a customer may not notice a small fraudulent charge, or a legitimate order may be declined and the customer simply leaves, so the system never learns it was wrong.
Fraud is also rare compared with normal transactions, so models must be built to cope with heavy imbalance. A system that called everything legitimate would be right nearly every time and useless.
False positives cost real money
Blocking a genuine customer is not a harmless error. They get annoyed, may abandon the purchase and sometimes the merchant for good. For many businesses, the revenue lost to wrongly declined orders can rival the fraud itself. Good teams track both numbers together and tune thresholds around business tolerance rather than chasing a single accuracy figure.
A softer response often beats a flat decline. Asking for extra authentication on a borderline payment keeps legitimate customers while stopping most thieves.
Latency is a constraint people forget. A payment decision usually has to come back in a few hundred milliseconds, so the model can only use data it can fetch quickly. Heavy analysis happens offline, and its results get stored as ready-made features, such as a customer’s average order value over the last month. Good transaction fraud detection is as much about plumbing as mathematics.
Consider a simple case. A customer who normally buys groceries locally suddenly orders several expensive electronics items to a new address from a device never seen before. Any one signal might be fine; together they raise the score and may trigger a one-time code. Buyers of such tools should ask the kind of questions found in seven questions worth asking before buying legal AI. The same tooling that helps defenders is spreading widely, since you can now describe an app and get one. For background, see Wikipedia’s article on machine learning.
Questions to ask a transaction fraud detection vendor
- How quickly does the model adapt when attackers change tactics?
- Can you see why a transaction was flagged, or is it a black box?
- How is performance measured on false positives, not just caught fraud?
- What data does it need, and where is that data stored?
- Can your own rules run alongside the model, and who controls the thresholds?
- How does it deal with new customers who have no history?
Where transaction fraud detection falls short
No transaction fraud detection system catches everything. Attackers test defenses with small purchases, use stolen real identities that look normal, and now use generated text and voices to pass manual checks. Social engineering, where a customer is tricked into sending money themselves, is especially hard because the payment looks authentic from the system’s view.
The best setups combine models with human reviewers for ambiguous cases, a feedback loop so decisions improve the system, and clear communication to customers. If you run an online shop, start by measuring your current decline rate and chargeback rate. Without those two figures, you can’t tell whether a new tool helps.
For a small merchant, the practical path is modest. Measure declines and chargebacks, ask vendors the questions above, and review results monthly. Transaction fraud detection improves with feedback, so tell your provider about mistakes, and remember that transaction fraud detection works best when people and software check each other’s work.
Image: Lotus Head from Johannesburg, Gauteng, South Africa / Wikimedia Commons, CC BY-SA 2.5.